[team]
Knowledgebase & Contacts CRM, on a real-time event pipeline
Two products built from scratch and still in production for millions of websites, kept in sync by a Kafka and MongoDB Change Streams pipeline.
Context
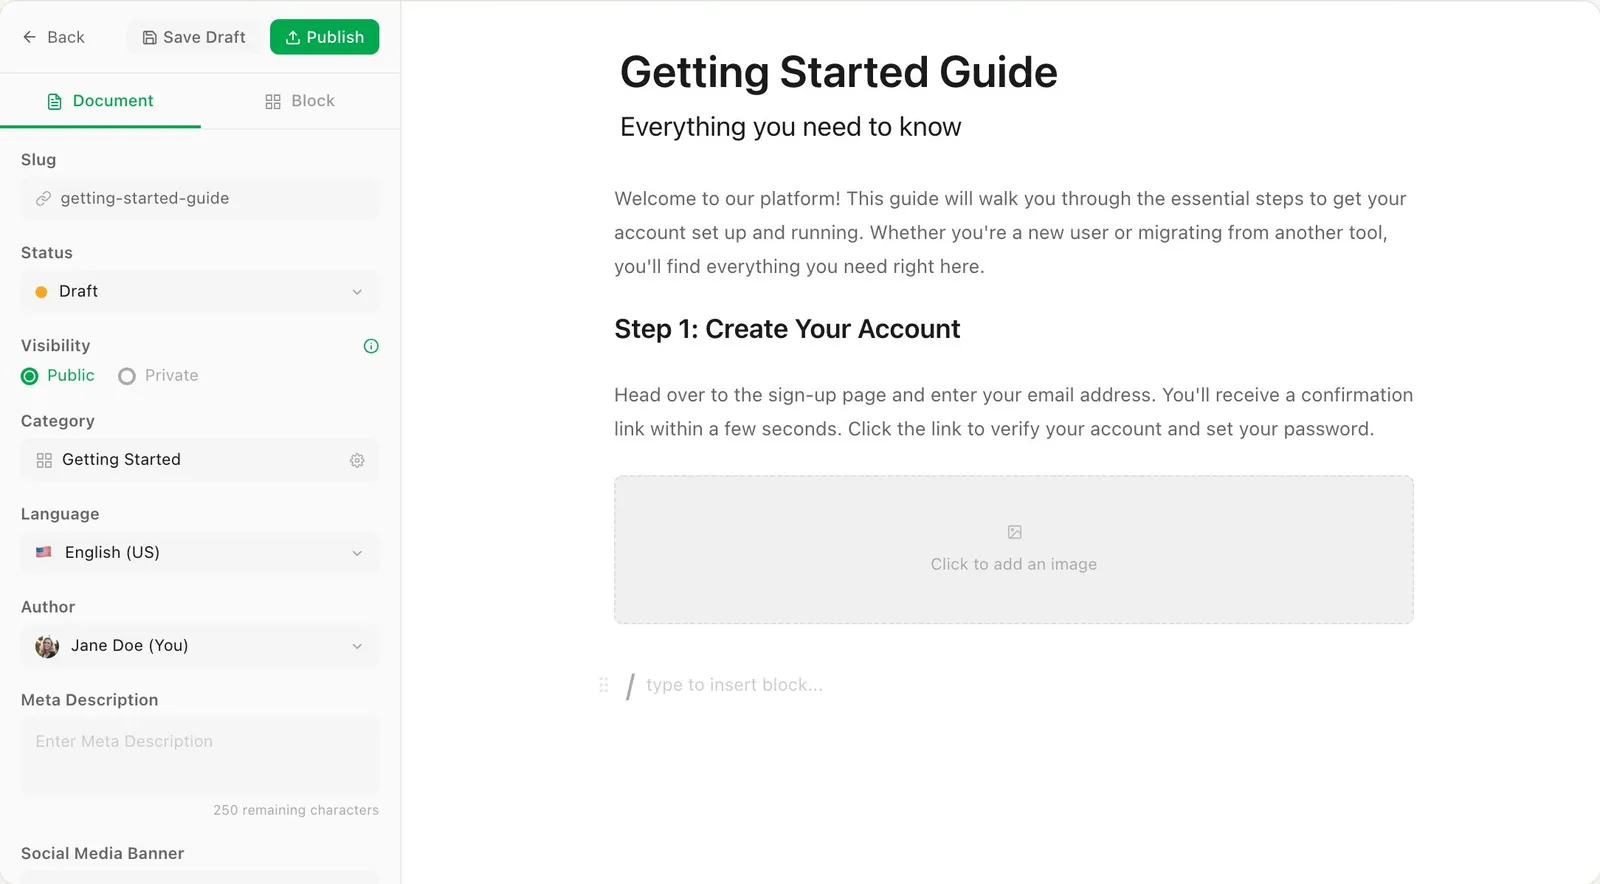
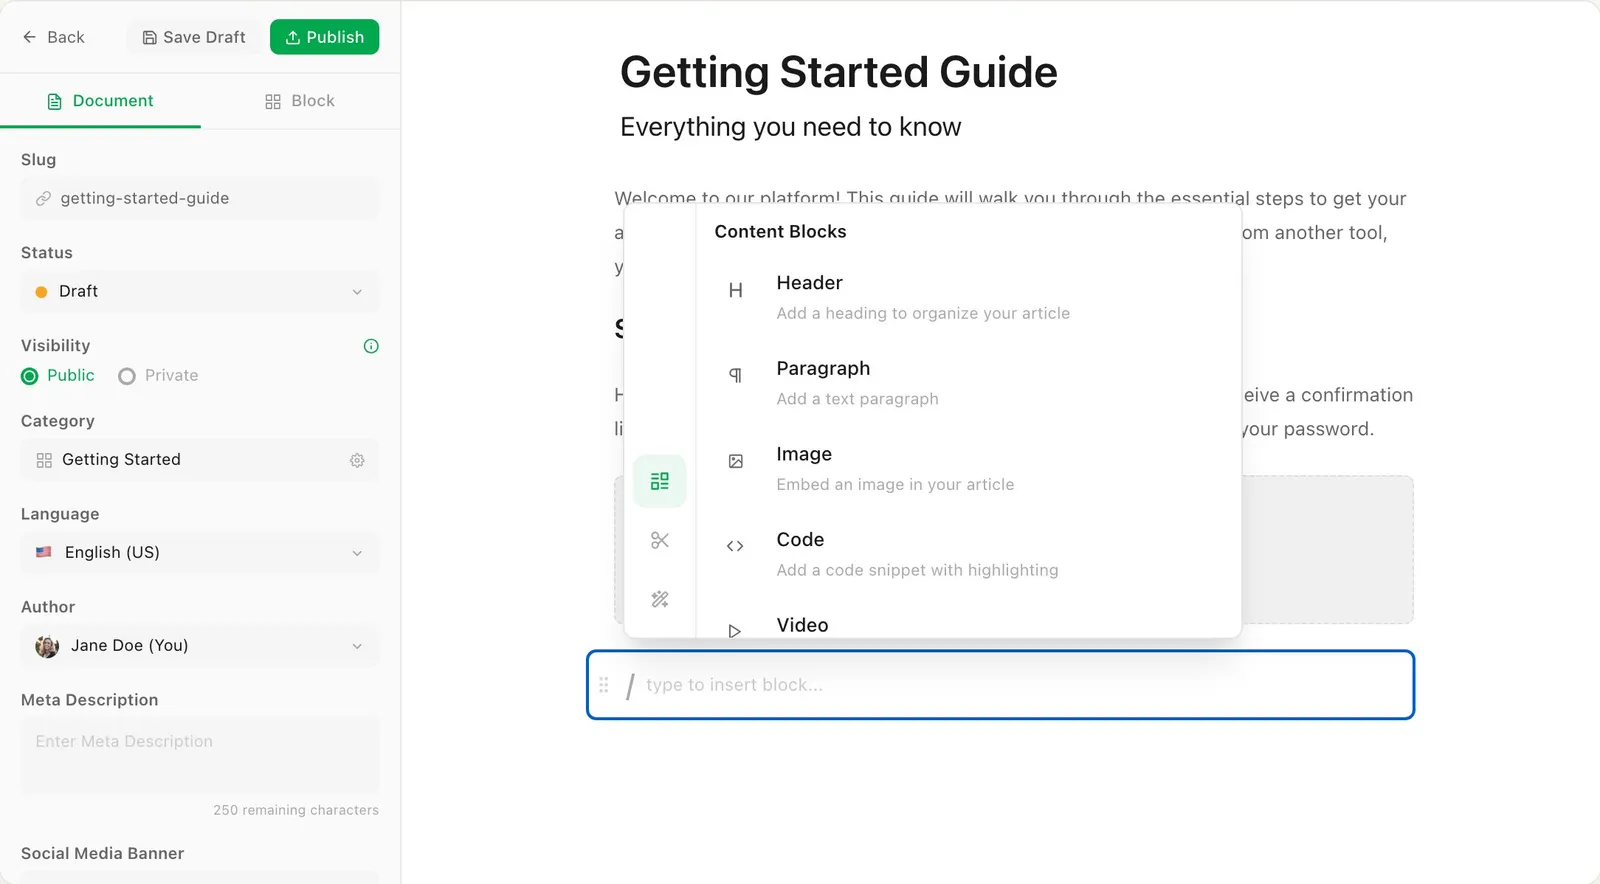
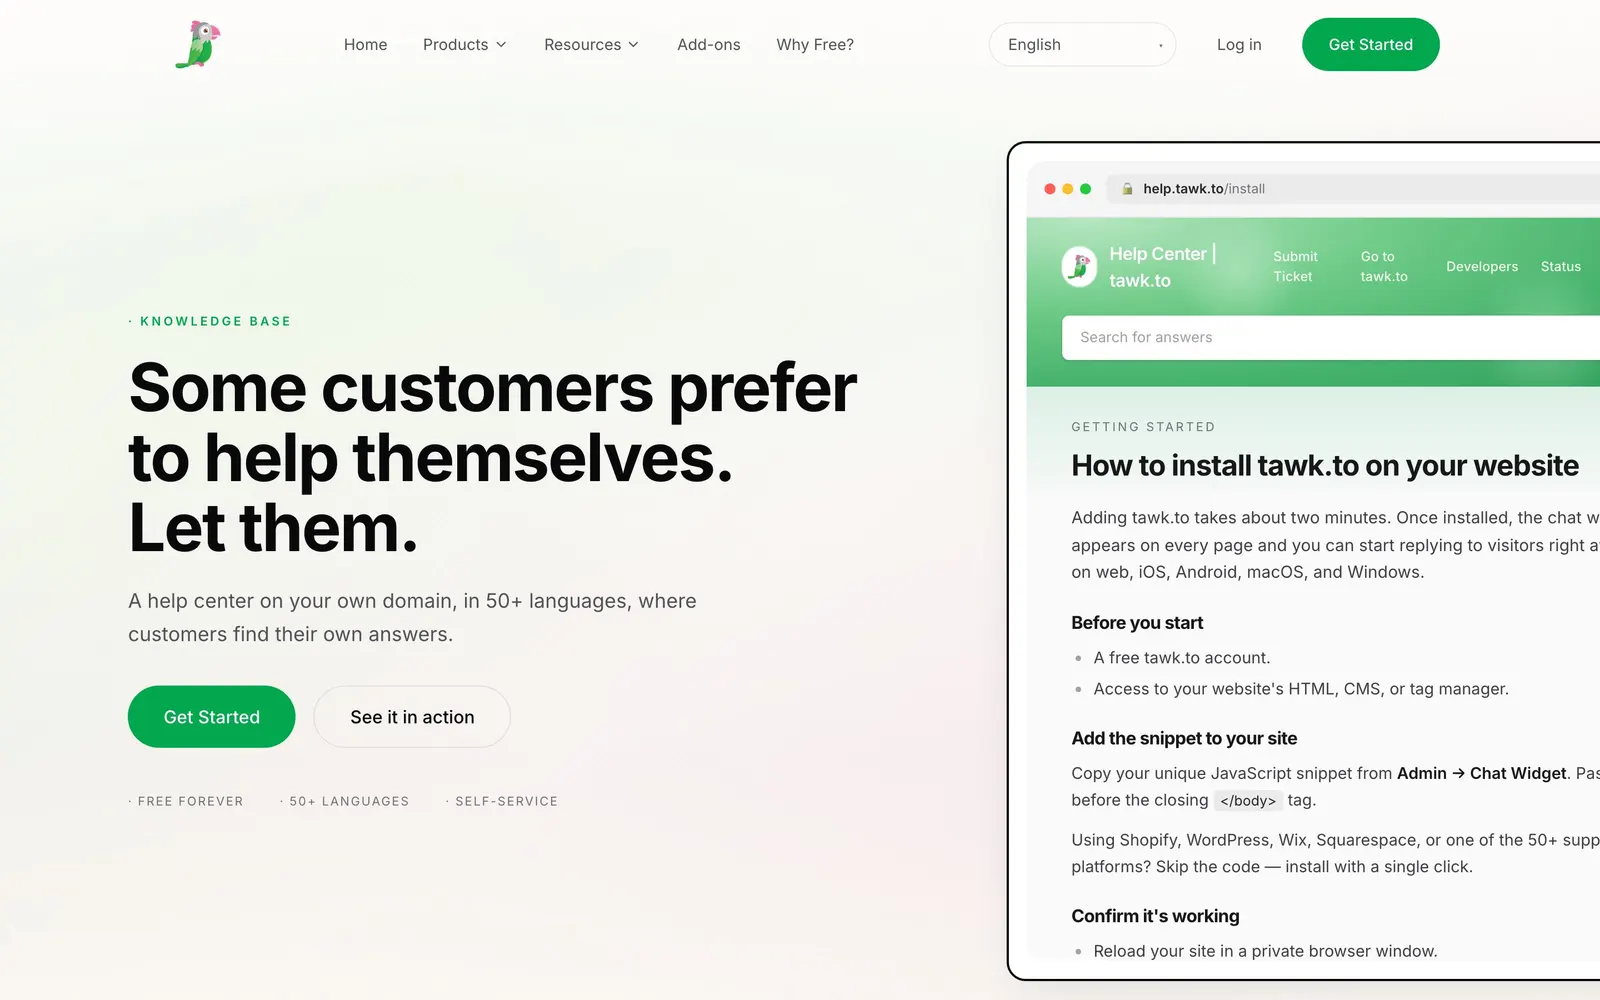
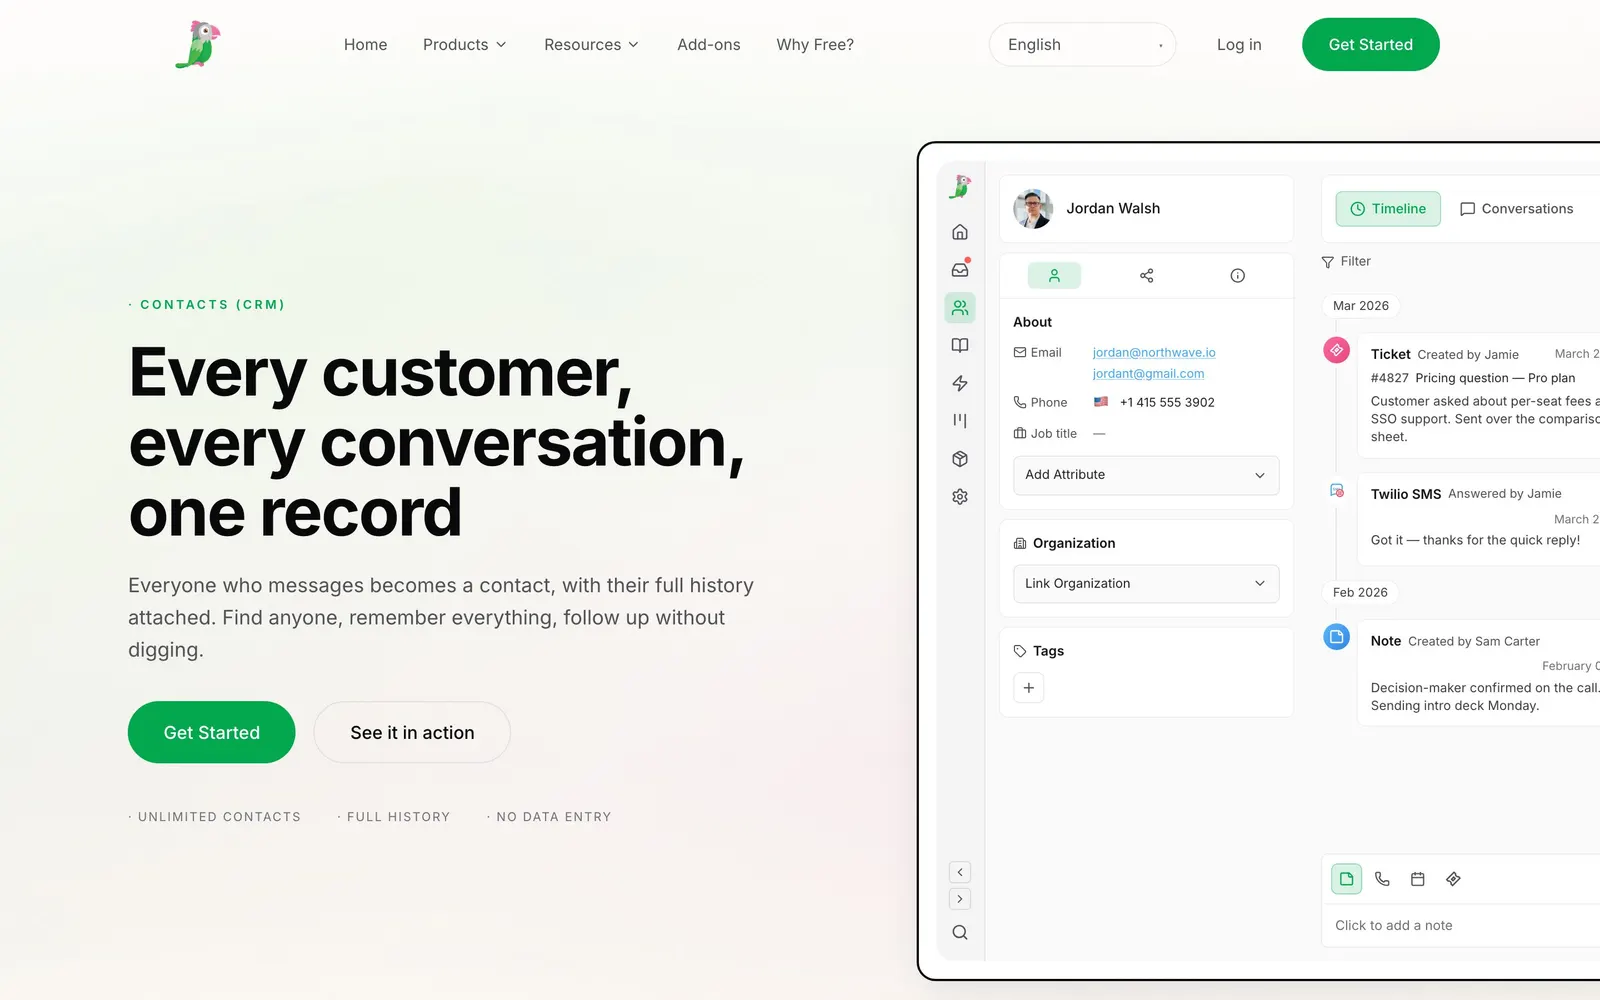
tawk.to customers use the platform to support their own visitors. They needed a self-service knowledgebase and a way to manage the contacts they talk to. Behind both sits tawk.to's backend of distributed services that need to react to each other's data. All of this was built by a small engineering team of 4–5 people working with the CTO.
Problem
Both features had to be built from nothing and hold up under the traffic of a platform used on millions of websites. Core workflows were tightly coupled, and the services needed to learn about data changes quickly and reliably without polling the primary database.
What I did
- Worked on the team that built the Knowledgebase service and the Contacts CRM from scratch, alongside the CTO.
- Developed backend features for both services in Node.js and MongoDB.
- Worked on the team that designed and built an event-driven service on Apache Kafka, decoupling core workflows and giving services a reliable way to communicate.
- Helped build the real-time data pipeline that captures changes with MongoDB Change Streams and publishes them to Kafka for downstream consumers.
- Implemented Elasticsearch-powered search and filtering.
- Kept 100% test coverage on the services I owned, to keep regressions out of production.
- Contributed to architecture discussions within the team.
Impact
- Both services are still active in production today.
- Customers can search and filter their knowledgebase and contacts quickly.
- Data changes reach downstream services with minimal latency, and decoupled workflows let the services evolve independently.